How to Track Brand Mentions in AI Search
How to track brand mentions in AI search: a repeatable prompt panel, the four states a tracker must keep apart, and how many checks make a mention rate real.
 Published Last updated 13 minute read
On this page 13 sections
- How do you track brand mentions in AI search?
- What's the difference between an AI mention and an AI citation?
- Why can't you set an alert for AI answers?
- How many checks do you need before the number means anything?
- How do you tell "not mentioned" from "we couldn't check"?
- How do you stop a tracker counting mentions that aren't mentions?
- Can you track how an assistant talks about your brand?
- Which AI assistants can you track, from ChatGPT to Perplexity?
- Which tracking tool fits: free checks, SEO suites or dedicated AI visibility tools?
- Five questions to ask before you monitor brand mentions with a tool
- What do you do when the mention is wrong?
- How does RankX AI record a brand mention?
- Separate the product match from the merchant recommendation
Short answer: To track brand mentions in AI search, ask a fixed set of buyer questions to ChatGPT, Gemini, Claude and Perplexity on a repeatable schedule. For each readable answer, record whether your brand is mentioned, its context, citations and position, and keep failed checks separate. Report the mention rate with its denominator and completion coverage for each assistant.
How do you track brand mentions in AI search?
You track brand mentions in AI search by asking AI assistants a fixed set of buyer questions on a schedule and recording every answer that comes back. There is no index to query and no alert to subscribe to. The only way to know what ChatGPT, Gemini, Claude or Perplexity says about your brand is to ask it and record what it said.
The result tells you how often your brand is mentioned, where your brand appears in AI answers and who appears beside it. Read across AI platforms, it is your brand visibility in AI answers, measured on questions you chose.
A working setup has five steps, and the order matters.
Write the prompt set
List the questions your buyers actually ask, not your keywords. A keyword is what someone types into Google; a prompt is a whole question.
Choose the assistants
Pick the AI platforms your buyers use and record each one separately, because they disagree with each other.
Set a schedule
Ask every prompt repeatedly on the same cadence, so a result can be read as a trend rather than an anecdote.
Record each answer
Note whether the brand was named, where it sat among the brands listed, which sources were cited and which competitors appeared.
Keep an honest denominator
Count how many checks ran, over what period, and how many produced no readable answer at all.
Most guides stop after the fourth step. The fifth decides whether the first four produce a number worth acting on, and this article spends most of its time there. Prompt research covers the first step in depth.
What's the difference between an AI mention and an AI citation?
An AI mention is an answer that names your brand in its text, and an AI citation is an answer that links one of your pages as a source. AI mentions and citations are different events, recorded separately. A brand monitoring setup that conflates them will misread its own data.
- Mention
The answer names the brand.
- Citation
The answer links to a source.
- Both
A named brand may also have a cited page.
Read the answer and its sources as separate observations.
They come apart constantly, in both directions. An answer can cite your page while recommending a competitor, which reads as a win in a citation report and is a loss in the market. An answer can name your brand from the model's training with no link at all, which a link-based tracker never sees.
For brand monitoring, record whether the brand name appears and what the AI says about it. Record source citations and merchant destinations separately. A mention does not establish that somebody saw, trusted or acted on the answer.
Outcome | What it is | What it tells you |
|---|---|---|
Mention only | The answer names your brand, with no link to you | The buyer heard your name |
Citation only | The answer links your page but names someone else | Your content was used, the credit went elsewhere |
Both | The answer names you and links you | The strongest single result |
The cited Seer study reports an association between citation status and organic click-through rates in its own sample. Cited and uncited queries can differ for other reasons, so use the study as context, not as a prediction of a fixed traffic increase for your store.
Read the companion figure carefully. On informational queries, Seer found a cited result still earns 38 per cent fewer organic clicks than a query that shows no AI Overview at all. Search Console impressions with no clicks sets out what a falling rate does and does not prove.
Why can't you set an alert for AI answers?
You cannot set an alert because a sampled answer is not a searchable record of everything an assistant has said. Unlike traditional search, AI-driven search leaves no public page to crawl. Some monitoring products alert on changes within the prompts they collect, but such an alert covers that observed panel, not every conversation about your brand.
The usual ways to monitor brand mentions online, such as web alerts and social listening, do not reach AI responses. Three consequences follow, and each breaks a habit carried over from classic monitoring for brand names.
- There is no backfill. A page published last March can be found today, but an answer given last March was never stored by anyone. Monitoring starts the day you start asking.
- Coverage is a choice. A web monitor sees whatever it crawls; an AI monitor sees only the questions it thought to ask. Your prompt set is your coverage.
- The same question does not give the same answer. Asking twice is two samples, not one confirmed reading.
That third point is not a rounding error. Ahrefs tracked more than 43,000 keywords carrying at least sixteen recorded AI Overviews each. It found an AI Overview has a 70 per cent chance of changing between observations, that 45.5 per cent of its cited sources are entirely new when it does, and that the average one is rewritten every 2.15 days.
AI systems behave the same way. Vismore's 750-response audit across five engines in March 2026 found the same prompt asked three times returned a meaningfully different brand list in 38 per cent of runs. SparkToro and Gumshoe put the stricter version at under a 1 in 100 chance that two runs of one prompt return the identical brand list.
How many checks do you need before the number means anything?
You need more checks than most advice suggests, and the right number depends on the decision you want to make. Published advice ranges from quarterly to daily and is usually asserted rather than derived. It can be derived, with caveats.
Start with the base rate, because every calculation needs it. Measured across prompt runs in RankX AI production on 27 August 2026, 87.8 per cent contained no answer mentioning the brand at all. That is a real answer, read, with the brand absent, so a typical mention rate in that data sits near 12 per cent.
The table below uses a simple binomial approximation: 1.96 times the square root of p(1-p)/n. It assumes independent checks of the same underlying probability. Different prompts and repeated answers do not automatically meet those assumptions, so the intervals are illustrations, not validated confidence limits for a mixed assistant panel.
Checks in the window | 95% confidence interval | Smallest change you can actually detect |
|---|---|---|
25 | plus or minus 12.8 points | 18.1 points |
50 | plus or minus 9.1 points | 12.8 points |
100 | plus or minus 6.4 points | 9.1 points |
200 | plus or minus 4.5 points | 6.4 points |
400 | plus or minus 3.2 points | 4.5 points |
800 | plus or minus 2.3 points | 3.2 points |
1,600 | plus or minus 1.6 points | 2.3 points |
One check means one prompt sent to one assistant once. Prompts multiplied by assistants and repeats gives the collection workload, not an effective statistical sample size. Keep per-assistant results and repeated prompt groups visible before interpreting a combined rate.
Two caveats, because a table like this gets quoted. The same prompt repeated correlates with itself, so real intervals are wider than shown. A mention rate far from 12 per cent also shifts the numbers, most at 50 per cent and least near the extremes.
An apparent change can come from a different prompt mix, unavailable checks or an assistant update. Inspect those before attributing movement to your site. Do not call a three-point change real merely because a pooled table suggests it should be.
How do you tell "not mentioned" from "we couldn't check"?
You store them as different values. This is the single most important design decision in any brand mention tracking setup, because it decides whether your visibility data can be trusted. Collapsing the two is how a provider outage renders as your brand disappearing from AI search.
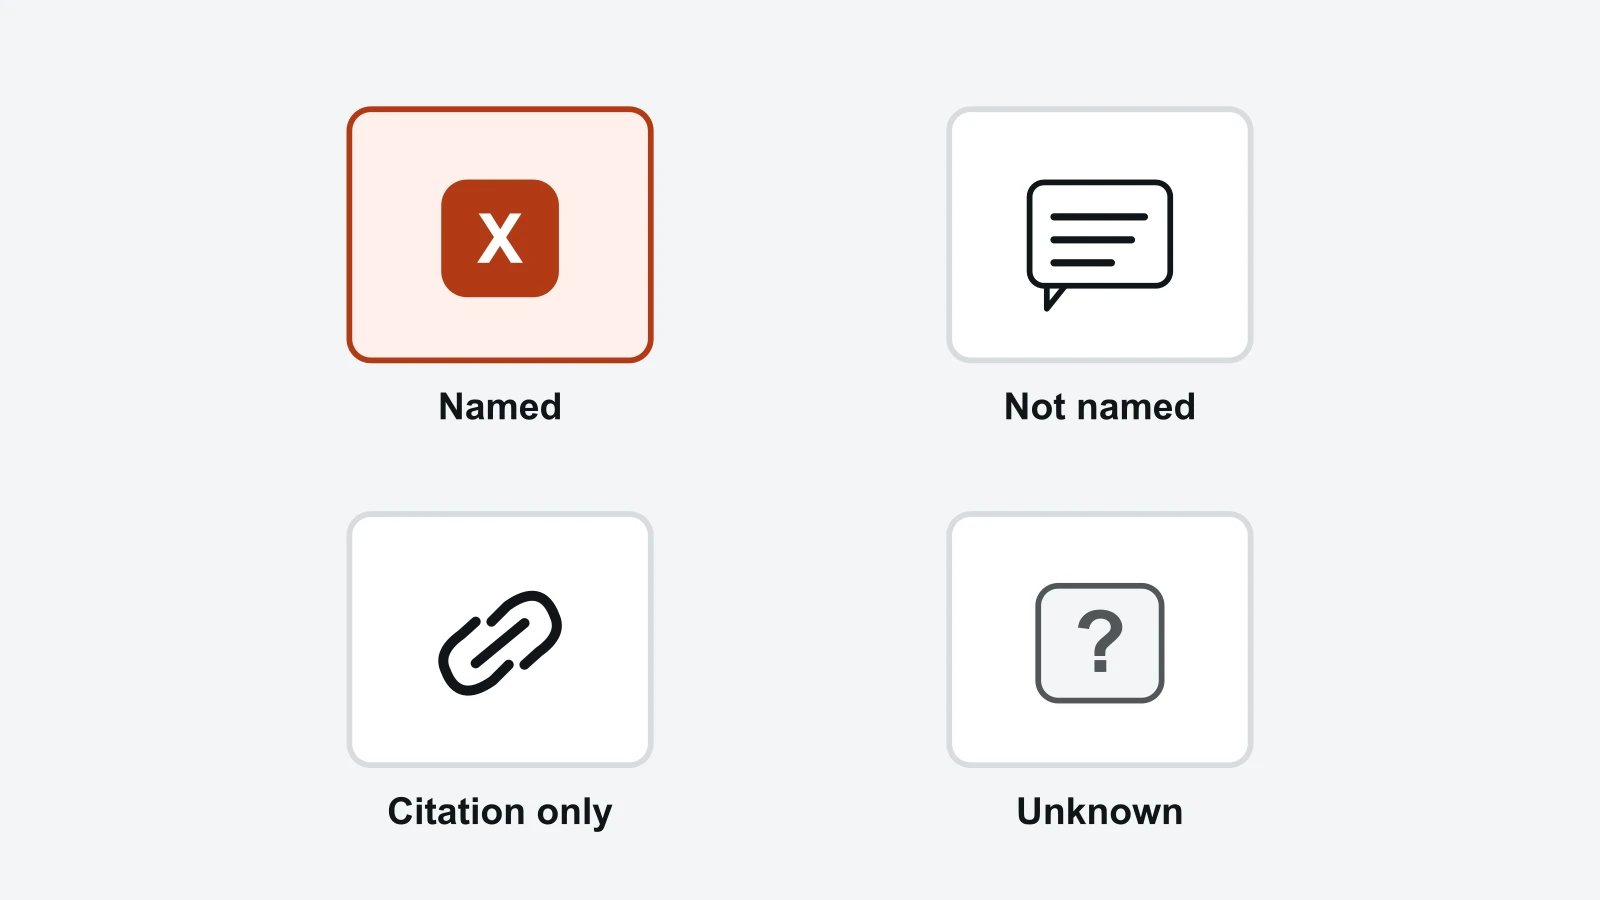
- Named
A captured answer names the brand.
- Not named
A captured answer does not name it.
- Unknown
The check could not establish an answer.
Unknown is not zero visibility. Preserve the underlying evidence for each outcome.
Four states are needed, not two.
State | What it means |
|---|---|
Mentioned | The answer named the brand, and the record can point at where. |
Not mentioned | An answer came back, it was read, and the brand is not in it. This is a real finding. |
Not assessed | The check did not run, or ran and produced no readable verdict. This is not a zero. |
Pending | The check is in flight and the answer has not returned. |
The third state is not a rare edge case. Assistants rate-limit, time out, refuse, and occasionally return something no parser can read, so any tracker running at volume records a share of checks with no verdict.
The fix lives in the arithmetic: a mention rate must divide by the checks that produced a verdict, not by the checks attempted. If only a third of the checks on an assistant carried a verdict, dividing by every attempt would report a rate around a third of its true value. Where nothing carries a verdict, the honest output is no number at all, not a zero.
So when you evaluate a tracking tool, ask to see a day when a provider was down and what the dashboard said that day. If the chart dipped, the tool is measuring its own reliability and labelling it your visibility.
How do you stop a tracker counting mentions that aren't mentions?
You bound what the tracker is allowed to record, in code, rather than trusting a language model's judgement about what it just read. The usual failure is not a missed mention. It is a model, or a naive string match, confidently recording mentions that never happened.
Two shapes cover most of it, and both are false positives generated by the question itself.
- A competitor whose name is a place, such as Leeds, on a project whose prompts read "best web design agencies in Leeds". A naive match fires on nearly every answer, because the answers repeat the word the question used.
- A competitor whose name is a generic phrase, such as Automation Agency, on a project whose prompts read "which AI automation agency should I hire". A naive match catches ordinary prose that names no company at all.
Neither is fixable with a stoplist, because the offending words are good brand names on a different project. The rule that works is contextual: a term that is ambient to the check, meaning it appears in the prompt itself or is the brand's own city or market, carries no signal when it turns up in the answer.
That rule has a deliberate trade-off. On a comparison prompt such as "how does X compare to Acme?", Acme is ambient, so a mention of Acme in the answer does not count. That loses a real mention, but a model naming a brand it was told to discuss is not evidence of organic visibility.
From RankX AIInspect the answer behind the mention.Use a fictional reporting check to test the denominator: 15 checks attempted, 12 with usable answers, three naming your brand.Explore AI visibility trackingCan you track how an assistant talks about your brand?
Yes, you can track what the AI recommends and how it describes you, but only when the sentiment is anchored to text that is genuinely about your brand. "We can't tell" must also be an allowed answer.
The naive approach sends the whole generative AI answer to a model and asks for a label. That produces a number for every check and means almost nothing, because an answer that praises three competitors and lists your brand in a table is not a positive mention of you.
RankX AI resolves brand sentiment from verbatim spans, and a proposed span clears six deterministic gates before it counts. The model proposes a label; the gates decide whether it stands.
- Verbatim. The span appears word for word in the stored answer.
- Anchored. The span is tied to the brand rather than floating in the answer.
- Subject. The brand is what the span is about, so a sentence praising a rival is discarded.
- Not a listing. A brand name in a table cell is not an opinion.
- Length. The span carries enough content to be informative.
- Confidence. The proposal clears a floor, below which the model is guessing.
Two design choices follow, and both are worth copying whatever tool you use. There is no neutral bucket; the fourth outcome is undetermined, and it is a real stored answer rather than a failure. AI brand sentiment covers what the measurement can and cannot support.
Which AI assistants can you track, from ChatGPT to Perplexity?
Track the AI tools your buyers actually use to research a purchase, and expect them to disagree. The assistants are not reached the same way, and citation coverage differs with the method, so no single figure describes all of them.
RankX AI tracks brand visibility across ChatGPT, Gemini, Claude and Perplexity, the major AI engines for buyer research, on the assistants you choose for each prompt. A store project starts with ChatGPT, Gemini and Perplexity, with Claude on request.
- Overlap is low. Across 100,000 identical prompts put to both, only 11 per cent of the domains cited by ChatGPT were also cited by Perplexity. Your brand visibility in ChatGPT is weak evidence about the others.
- Citation coverage varies widely. Some assistants return structured sources on almost every answer, some rarely, some never. A citation metric can look strong on one and empty on another for reasons unrelated to your visibility.
- Market coverage is not universal. Not every assistant serves every market, and an unserved market should be recorded as unsupported rather than quietly answered from somewhere else.
Google AI Overviews and AI Mode are AI search surfaces inside Google, and they are deliberately not in that list. An AI Overview is triggered by a search rather than prompted like an assistant, so RankX AI tracks it through the rank-tracking pipeline against your tracked keywords. The free AI Overview Checker shows whether a keyword triggers one and who is cited inside it.
Which tracking tool fits: free checks, SEO suites or dedicated AI visibility tools?
Five kinds of tool can track brand mentions in AI search, from a free spreadsheet to a dedicated AI visibility tracker. Pick by how many prompts you need to repeat, how much of the answer you need to keep and whether you need to track your brand against named competitors.
Route | What you get | Where it stops |
|---|---|---|
A manual panel in a spreadsheet | Free, and you read every answer yourself | Operator time, and each assistant's usage limits |
Google Search Console | Free search performance data that includes AI Overviews and AI Mode | No separate AI filter and no brand mentions |
A free AI visibility check | A snapshot for one keyword or question | A visibility checker shows one moment, not a trend |
SEO suites | AI SEO tracking beside rank tracking, such as the Semrush AI Visibility Toolkit or SE Ranking's AI Visibility Tracker | Check which assistants and how many prompts each plan covers |
Dedicated AI visibility tools | Prompt panels that monitor brand visibility across AI search engines, such as Peec AI or Profound | Check the denominator and the outage behaviour |
Google Search Central's page on AI features says sites appearing in AI Overviews and AI Mode are counted in the Search Console Performance report under the Web search type. That gives you the traffic total, not a list of the answers that named you.
RankX AI keeps assistant answers, AI Overviews and Google rankings in one product, with the stored answer behind every number, so you can find visibility gaps and open the answer that shows each one. Our roundup of AI visibility tools compares ten of them from their own pricing pages.
Five questions to ask before you monitor brand mentions with a tool
Every vendor in this category will show you a share of voice chart. These five questions separate the tools measuring your brand from the ones measuring their own pipeline, and we would expect a good answer to all five, including from us.
- What does the chart do on a day a provider is down? If it dips, failed checks are being counted as absences. Ask to see a real outage day.
- What is the denominator? A mention rate must divide by checks that produced a verdict. When none did, the right answer is no number, not zero.
- Can a brand be recorded as mentioned when its name is not in the answer text? If yes, a model's guess is being stored as a fact.
- Is a competitor credited when the prompt named that competitor? If yes, comparison prompts are inflating everyone, including you.
- How many checks sit behind this number? Cross-check it against the table above. With few checks in the window, a percentage to one decimal place is decoration.
A sixth, if the tool reports sentiment: ask what it is computed from and what it displays when the evidence does not support a verdict.
What do you do when the mention is wrong?
Treat an incorrect mention as a claim to investigate, not a number to log. Save the answer and inspect any sources it provides. The error may involve an outdated source, an unsupported inference or an ambiguous product match, so do not assume every error traces to one published page.
Correct a verified source error where you control the page, or request a correction through the source's normal process. State the accurate product fact clearly and keep the evidence. Repeat comparable checks later, because neither the time of retrieval nor the time an answer changes is guaranteed.
This is reputation work rather than measurement work. Online reputation management covers the full sequence, including what to do when the source is one you do not control.
How does RankX AI record a brand mention?
RankX AI stores each answer and records, from it, whether your brand was mentioned, where it sat among the brands named, which sources were cited, which competitors appeared and how the answer talked about the brand. The stored answer sits behind every number, so any figure can be checked against the text it came from. Check your plan's cadence and credit allowance before scheduling a panel.
Three properties decide whether a number is trustworthy.
- A brand whose name does not appear in the answer text cannot be recorded as mentioned. That is structural in the code, not a filter someone remembers to switch on.
- "We did not look" and "we looked and you were not there" are different values everywhere in the product, and they are drawn differently.
- Cadence and assistant targeting are set per prompt, so the set behind two periods can differ, and a comparison states the set it is actually comparable across.
AI Visibility carries the assistant side of this, and AI share of voice covers how individual mentions aggregate into a number you can report. If you are starting from nothing, start with the prompts rather than the tooling: the questions buyers ask when they use AI to choose.
Separate the product match from the merchant recommendation
Keep a three-part record for every shopping observation: the exact product and variant, the brand named in the answer, and the merchant receiving the destination link. If a matching product sends the buyer to another retailer, record that destination. Product visibility and a link to your own store are different results, even when the product name is identical.
- Brand
Was the brand actually named?
- Merchant
Which store was identified or linked?
- Outcome
Was a visit or order measured separately?
Keep that record per assistant and retain the three unavailable checks; pooling them or treating them as absence can hide a collection problem.
Use a fictional reporting check to test the denominator: 15 checks attempted, 12 with usable answers, three naming your brand. The observed mention rate is 3/12, or 25 percent, and completion coverage is 12/15, or 80 percent, not a 20 percent mention rate.
Report each assistant on its own line, with the unavailable checks shown beside the rate rather than folded into it.
Next, inspect shopping observations or calculate the denominator.
Questions about AI Visibility & Analytics
How do I measure how often AI assistants mention my brand?
Divide readable answers naming your brand by readable answers with a usable verdict. State the prompts, assistant, period, numerator and denominator, and report failed or unavailable checks separately. This measures your defined panel, not the proportion of all buyers who saw the brand.
How often should you check brand mentions in AI search?
Choose a consistent cadence that fits the decision, available credits and your ability to inspect answers. Repeated checks of one prompt are correlated, so 200 checks or a particular percentage change is not a universal reliability threshold. Keep the same panel and compare each assistant separately before drawing a conclusion.
Can you track brand mentions in AI search for free?
You can run a small manual panel and record answers in a spreadsheet, subject to each assistant's access and usage limits. That takes operator time. Automation can make repeated collection practical, but it is not a prerequisite for a useful manual pilot.
How many prompts should you track?
Enough to cover the questions that decide a purchase, which is usually dozens rather than hundreds. Coverage matters more than volume: a prompt set that misses the comparison question your buyers actually ask will report a healthy number while you lose the deal. Start with what your sales team hears most often.
Does RankX AI track Google AI Overviews as an AI assistant?
No. An AI Overview is triggered by a search rather than prompted like an assistant, so RankX AI tracks it through the rank-tracking pipeline against your tracked keywords instead. The two surfaces answer different questions, and combining them into one visibility figure produces a number nobody can interpret.
How many AI assistants does RankX AI track?
Four: ChatGPT, Gemini, Claude and Perplexity, and you choose which of them each prompt runs on. A store project starts with ChatGPT, Gemini and Perplexity, with Claude on request. The assistants are not all reached the same way, and what each exposes, citations especially, differs with the method.
Is a brand mention in an AI answer worth more than a backlink?
There is no universal exchange rate, because a mention, source citation, merchant link and backlink serve different purposes. Inspect the claim and destination, then measure any recorded visits or business outcomes separately. Neither a mention count nor a citation count establishes what a buyer saw or did.
Sources
- RankX AI production measurement, 27 August 2026: 87.8% of prompt and run units contained no mentioning answer Checked 2026-10-17.
- Ahrefs, AI Overviews change every 2 days: 70% change rate between observations, 45.5% citation turnover, 43,000+ keywords (opens in a new tab) Checked 2026-10-17.
- Seer Interactive, AIO Impact on Google CTR: 2026 Update (24 Apr 2026). 53 brands, 5.47M queries, 2.43B organic impressions, full-year 2025 plus Q1 2026. Cited in an AI Overview: 120 per cent more organic clicks per impression than not cited; on informational queries still 38 per cent below results with no AI Overview (opens in a new tab) Checked 2026-10-01.
- SparkToro and Gumshoe, AI brand-recommendation consistency study, 2,961 runs (opens in a new tab) Checked 2026-10-17.
- Profound, citation overlap between ChatGPT and Perplexity across 100,000 identical prompts (vendor study) (opens in a new tab) Checked 2026-10-17.
- Vismore, 50x5x3 AI mention audit, 750 responses, March 2026: 38% of repeated runs returned a meaningfully different brand list (vendor study, competitor) (opens in a new tab) Checked 2026-10-17.
- OpenAI: shopping with ChatGPT Search (opens in a new tab) Checked 20 Oct 2026.
Asif Syed is the founder and CEO of RankX AI, the AI search visibility platform. He builds the product and writes here about GEO, AI search measurement and WordPress.
CoversThis article covers the AI Visibility & Analytics topic, the AI Visibility feature and the AI Overview Checker tool.
Terms usedAI Mention, AI Citation, AI Brand Sentiment, Unlinked Brand Mention, AI Share of Voice, Citation Rate, Prompt Volume and Synthetic Query.
Read this page asMarkdown: /blog/track-brand-mentions-ai-search.md.
All articlesEverything RankX AI publishes is listed on the blog index.
Ask an assistantAsk ChatGPT (opens in a new tab), Ask Claude (opens in a new tab) or Ask Perplexity (opens in a new tab).
Preferred sourceIf Google is your front door, you can add RankX AI as a preferred source (opens in a new tab), which asks your own results to surface more of what we publish.