How AI Crawlers Read Your Site
Which AI crawlers exist, their user agents, what they fetch, which of them run JavaScript and which do not, and how to verify your pages are reachable.
 Published Last updated 7 minute read
On this page 8 sections
- What is an AI crawler?
- Which AI crawler bots and user agents matter for your site?
- How do AI crawlers differ from search engine crawlers that index the web?
- Do AI crawlers execute JavaScript?
- How do you manage AI crawler activity: allow or block?
- What changed at Cloudflare on 15 September 2026?
- How do you verify what each bot can crawl?
- Compare the initial product response with the page a buyer sees
Short answer: AI crawlers are bots that fetch web pages for AI systems, for three jobs: collecting training data, building the index AI search answers from, and fetching a page live when a user asks. Most of them read only the raw HTML your server sends and run no JavaScript, so a fact that appears only after scripts run is invisible to them.
What is an AI crawler?
An AI crawler is a web crawler that fetches pages for an artificial intelligence system rather than for a classic search index. Each one announces itself with a user agent string, such as GPTBot or ClaudeBot, and that name is what every control below keys on.
AI companies run these crawler bots for three distinct jobs, and each job comes from a different bot with a different rule. The table shows how each one collects web content.
Purpose | What the bot does | Examples |
|---|---|---|
Training | Collects data for training the large language models behind generative AI | GPTBot from OpenAI, ClaudeBot, meta-externalagent, CCBot |
Search indexing | Builds the index behind generative search results, so pages can be cited and linked | OAI-SearchBot, Claude-SearchBot, PerplexityBot, Googlebot |
User-triggered retrieval | Fetches a page as a real-time query runs, giving the assistant information beyond its training data | ChatGPT-User, Claude-User, Perplexity-User |
The purposes matter more than the names. The data collection you might object to is LLM training, while the AI crawler activity you probably want is search indexing and retrieval augmented generation, the requests that surface websites in search results and AI answers. Block by purpose, not by vendor.
Which AI crawler bots and user agents matter for your site?
The crawlers that matter are the ones each major vendor runs for search, because they decide whether AI assistants can cite you. Every major vendor now runs separate bots for separate purposes, so a rule for one purpose does not apply to the others.
Vendor | Training | Search | User fetch |
|---|---|---|---|
OpenAI | |||
Anthropic | Claude-SearchBot | Claude-User | |
Perplexity AI | None: PerplexityBot is not used for AI foundation models | Perplexity-User | |
Google-Extended, a control token that never fetches | Googlebot, which also serves AI Overviews and AI Mode | Google-Agent and Google-GeminiNotebook | |
Meta Platforms | meta-externalagent | meta-webindexer | meta-externalfetcher |
Amazon | Amazonbot | Amzn-SearchBot | Amzn-User |
Apple | Applebot-Extended, a control token that never fetches | Applebot | None |
Mistral | MistralAI-Training | MistralAI-Index | MistralAI-User |
Common Crawl's CCBot collects an open dataset widely used for training, and DuckDuckGo's DuckAssistBot fetches for its AI answers. That brings the documented roster to 25 tokens. Two more cannot be verified: ByteDance publishes no documentation for Bytespider, and xAI documents no crawler token, so no robots.txt rule can name Grok.
Two rules surprise people. Google-Extended controls Gemini training and grounding, and it does not affect Google Search, so blocking it does not remove you from AI Overviews. Applebot follows your Googlebot rules when your robots.txt does not name it.
The AI Crawler Access Checker carries the full table with each vendor's documentation linked. Read it before you copy a block list, because many lists circulating online still show the 2024 roster.
How do AI crawlers differ from search engine crawlers that index the web?
Traditional search engine crawlers exist to send you human traffic. Googlebot fetches so that search results can rank your pages and readers can click through.
Most AI crawler traffic has no such loop. A training crawler does its scraping and the value flows into model training, with no visit sent back. Cloudflare reports that some of the most heavily crawled categories have seen human traffic fall by as much as 40 percent in under a year.
The mix of web traffic from bots has moved fast enough that year-old advice describes a different web. Cloudflare's bot report of 1 July 2026 puts requests from AI training crawlers at 52 percent of all crawler requests in June 2026, up from 22 percent in spring 2025. It also says more than half of traffic on the internet is now non-human.
Search crawlers from the same AI platforms sit between the two extremes. They index so that AI assistants can cite and link you, the closest the new bots come to the old bargain, and they are the ones a visibility decision should protect.
Different crawlers create very different request patterns. Check your own response times, failed requests and traffic spikes before changing rate limits, so you avoid overwhelming servers without blocking verified AI search bots. A spike or a user agent name does not tell you what content was used in an answer, and AI bot tracking shows how to verify each request against the vendor's published IP ranges.
Do AI crawlers execute JavaScript?
Almost none of them do. Vercel and MERJ measured Vercel's network for the month before publishing on 17 December 2024 and recorded GPTBot at 569 million requests, Claude at 370 million, AppleBot at 314 million and PerplexityBot at 24.4 million.
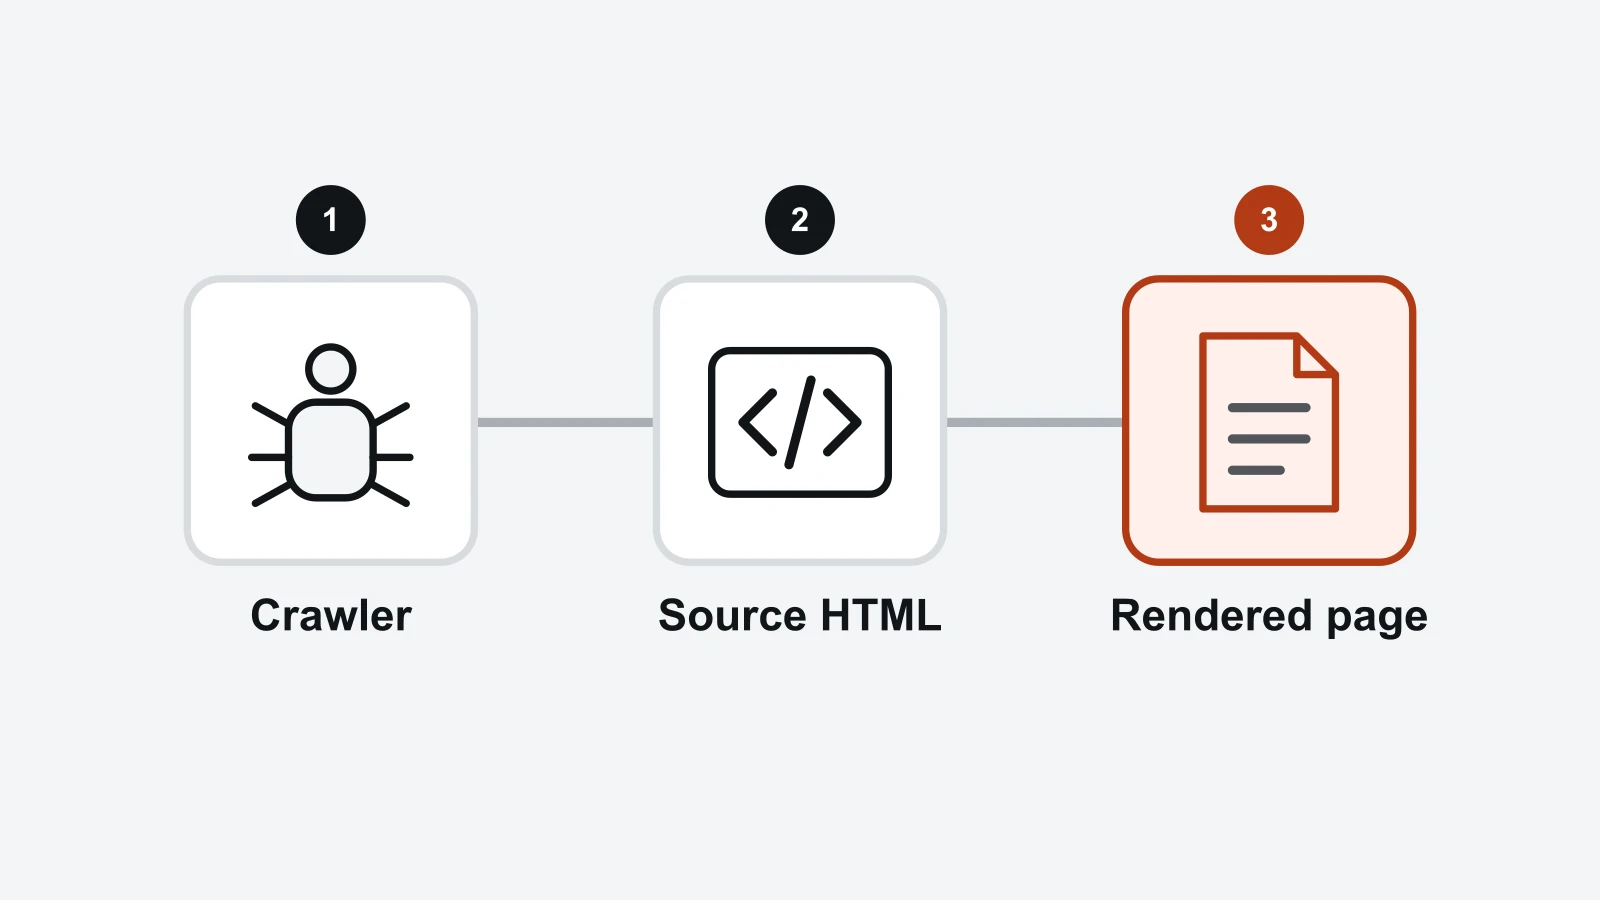
- Initial HTML
Inspect the response before JavaScript.
- Rendered page
Check what the browser adds.
- Important facts
Verify that key content is actually available.
Do not infer every crawler capability from a successful browser render.
GPTBot and ClaudeBot download JavaScript files, in 11.50 and 23.84 percent of requests, and execute none of them. Those volumes are now 22 months old, so read them as scale rather than as today's traffic. The rendering split is the part that has held.
A separate searchVIU survey of 23 crawlers, last revised in November 2025, found 69 percent could not execute JavaScript. The exceptions are the search engines' own crawlers: Googlebot renders, and Apple says Applebot may render your page in a browser.
The practical rule is simple. Put every fact you want quoted in the HTML your server sends: product names, prices, specifications and answers. A fact injected by scripts after load does not exist for GPTBot, ClaudeBot or PerplexityBot.
searchVIU tested structured data from the same angle. None of the AI systems it tested extracted a price that existed only in JSON-LD; they read the visible page. Keep schema for rich results, and keep the facts in the text.
What about agentic browsers?
AI-powered agent modes such as ChatGPT agent, Perplexity Comet and Claude operating a browser drive real browsers and do render JavaScript. Each is a per-user session, an AI agent acting on a page it was already sent to.
Retrieval and citation, the systems that decide whether anyone is sent to your page, still run on the raw HTML. Build for the crawler, and the agent inherits it.
From RankX AIInvestigate the page behind the rendered product.Check the intended crawler policy and actual access evidence, then fix the confirmed template problem with the site team.Explore website auditsHow do you manage AI crawler activity: allow or block?
Allow the search crawlers if you want to be cited, and decide on training crawlers separately. Choose a policy for each purpose, then check the vendor's current controls and your live responses.
Your goal | Search bots | Training bots | User fetchers |
|---|---|---|---|
Appear in AI answers and Google | Allow | Your choice | Allow |
Stay out of model training, stay citable | Allow | Disallow by name | Allow |
Keep content private | Use logins or access controls | Use logins or access controls | Use logins or access controls |
Many sites block training crawlers while staying retrievable. The reverse mistake, blocking a search bot to make a point about training, removes the site from the AI answers this whole discipline is about.
robots.txt is not the only thing answering the question. Cloudflare reported in September 2026 that 17 percent of the sites on its network block AI training in some way, while fewer than 1 percent block search bots. Many of those blocks live at the edge, not in a robots.txt rule anyone wrote.
One more control is worth knowing and worth grading honestly. Cloudflare's Content Signals Policy, published 24 September 2025, extends robots.txt with search, ai-input and ai-train signals, each yes or no. It says what a crawl may be used for, but no engine documents honouring it, so add it for the licensing position rather than for visibility.
On WordPress the purpose split is easy to get wrong, because the block lists popular plugins install also disallow search crawlers. Blocking AI crawlers in WordPress audits those lists token by token.
What changed at Cloudflare on 15 September 2026?
Cloudflare now classifies a crawler by every behaviour it has, so choosing Block for AI training also stops Googlebot, Applebot and Bingbot. Disallow AI Training, added the same day, refuses training through robots.txt and keeps them crawling for search.
Existing training blocks were migrated to Disallow AI Training, including the legacy Block AI bots preset. So blocking AI training at the edge is now a decision about Google Search only when you choose Block.
A robots.txt that allows Googlebot does not stop an edge rule refusing it, and that gap shows only in a live fetch. Blocking AI crawlers at Cloudflare covers the settings, the presets and what to choose instead.
How do you verify what each bot can crawl?
Verify from the request outward: the rules, the HTML, then the responses crawlers really received. Four checks settle it for most sites.
- Request
Check agent and response status.
- Document
Inspect the actual served content.
- Resources
Identify blocked or unavailable dependencies.
Use the observed response rather than assuming the crawler saw your browser view.
Read your rules as each bot does
Run the AI Crawler Access Checker to see which bots robots.txt allows, which it blocks, and whether a live request as each bot gets a 200.
View the source
Open view source on your key pages and search for the sentences that must be quotable. If they are not in the raw HTML, nothing downstream matters.
Check the logs
Look for retrieval bots such as OAI-SearchBot, Claude-SearchBot and PerplexityBot in your server or CDN logs, returning 200s, and verify each against the vendor's published IP ranges.
Serve them cheaply
Cache pages for crawlers and return fast 200s, rather than blocking search bots to save server load.
The free AI Crawler Access Checker runs the first check in seconds. RankX AI also re-reads your robots.txt, llms.txt and homepage every day on every account and reports when crawler access gets worse.
Everything a crawler needs is also everything extraction needs, so this work compounds. The GEO guide covers what to do with access once it is verified, and Website Audit runs these checks across the whole site.
An llms.txt file is not part of this check. No major AI crawler documents reading it, so it cannot fix a blocked or script-only page.
Access is only the first gate. A crawler fetching a page decides nothing about whether the engine keeps it, and how to check when Google indexed a page covers the reading that comes after the fetch.
Compare the initial product response with the page a buyer sees
Choose a product whose important specifications appear in tabs or after an interaction. Compare the initial HTML response with the rendered page, and check whether the website content, links and current product facts are in both.
An empty placeholder in the response is a technical lead, not proof of what every assistant sees. Confirm the cause against your crawler rules and logs before your developer changes the product template.
Keep public product content separate from account and checkout pages. Recheck the response and the storefront after a change, because access, extracted facts, AI selection and orders are four different outcomes.
Next, verify crawler requests or review WordPress product templates.
Questions about AI Search Essentials
Is ChatGPT a web crawler?
No. ChatGPT is an assistant, and OpenAI's crawling is done by named bots: GPTBot collects content for model training, OAI-SearchBot builds the index ChatGPT search answers from, and ChatGPT-User fetches a page when a user asks about it. When a log says ChatGPT visited, one of those user agents is what it shows.
Does blocking GPTBot remove my site from ChatGPT?
No. GPTBot is OpenAI's training crawler, and ChatGPT search retrieves through OAI-SearchBot, which has its own robots.txt rule. Blocking GPTBot opts you out of training while you stay eligible for answers; blocking OAI-SearchBot removes you from ChatGPT search answers, apart from navigational links.
Should I allow AI crawlers?
Allow the search crawlers if you want to appear in AI answers: OAI-SearchBot, Claude-SearchBot, PerplexityBot and Googlebot. Training crawlers are a separate choice about how your content is used, and blocking them does not remove you from AI search. Decide per purpose, not per vendor.
Why does my JavaScript content rank in Google but never get cited by assistants?
Rendering can be one cause, but a missing citation does not prove it. Compare the important fact in the initial HTML with the browser view, and check the responses crawlers actually received. Fixing an inaccessible fact makes it retrievable; it does not make any assistant cite it.
How many AI crawlers are there?
The AI Crawler Access Checker's roster, verified against vendor documentation on 13 September 2026, lists 27 bots from 12 vendors. Twenty-five of them are documented by their vendor; Bytespider has no official documentation and xAI documents no token at all, so no robots.txt rule can name Grok.
Can robots.txt keep AI systems off my site completely?
No. It is a request to compliant crawlers, and it does not authenticate a visitor or protect private data. User-triggered fetchers such as ChatGPT-User and Perplexity-User say robots.txt may not apply to them, so use real access controls for private pages.
Sources
- Vercel and MERJ, The Rise of the AI Crawler, 500M+ fetches (opens in a new tab) Checked 13 Sep 2026.
- searchVIU, AI crawlers and JavaScript rendering. 23 crawlers, 69% cannot execute JavaScript. Last revised 17 Nov 2025 (opens in a new tab) Checked 13 Sep 2026.
- OpenAI bot documentation (opens in a new tab) Checked 2026-10-21.
- Anthropic crawler documentation (opens in a new tab) Checked 13 Sep 2026.
- Perplexity bot documentation (opens in a new tab) Checked 13 Sep 2026.
- Cloudflare, Your site, your rules: new AI traffic options (1 Jul 2026). The ad-page plan for new domains that the 15 Sep 2026 presets replaced, and the multi-purpose rule naming Googlebot, Applebot and BingBot (opens in a new tab) Checked 13 Sep 2026.
- Cloudflare docs, Block AI Bots. The legacy preset blocks training crawlers and excludes mixed-purpose Search+Training bots; deprecating 15 Sep 2026 (opens in a new tab) Checked 13 Sep 2026.
- Cloudflare, Have it both ways (15 Sep 2026). The two presets offered to new domains by whether the site earns money from ads, Disallow AI Training, Block reaching Googlebot, Applebot and Bingbot, the migration of existing training blocks, and 17% of sites blocking AI training against less than 1% blocking search bots (opens in a new tab) Checked 1 Oct 2026.
- Cloudflare, Content Independence Day one year on (1 Jul 2026). AI training at 52% of crawler requests in Jun 2026 from 22% in spring 2025, mixed-use crawlers over 36% of activity, over 20% of the web behind Cloudflare, over 50% of internet traffic non-human (opens in a new tab) Checked 13 Sep 2026.
- TechCrunch on Cloudflare's policy (1 Jul 2026). Reports a free-tier scope the primary sources do not state; recorded as the discrepancy, not relied on (opens in a new tab) Checked 13 Sep 2026.
- searchVIU, what engines really see (JSON-LD-only content unread) (opens in a new tab) Checked 13 Sep 2026.
- Google Search Central: ecommerce site structure (opens in a new tab) Checked 20 Oct 2026.
- Google Search Central: robots.txt scope and limitations (opens in a new tab) Checked 2026-10-21.
- Perplexity: documented crawlers and request verification (opens in a new tab) Checked 2026-10-21.
Asif Syed is the founder and CEO of RankX AI, the AI search visibility platform. He builds the product and writes here about GEO, AI search measurement and WordPress.
CoversThis article covers the AI Search Essentials topic, the Website Audit feature and the AI Crawler Access Checker tool.
Terms usedGPTBot, ClaudeBot, PerplexityBot, OAI-SearchBot, ChatGPT-User, AI Crawler, Google-Extended, Robots.txt and Server-Side Rendering (SSR).
Read this page asMarkdown: /blog/how-ai-crawlers-read-your-site.md.
All articlesEverything RankX AI publishes is listed on the blog index.
Ask an assistantAsk ChatGPT (opens in a new tab), Ask Claude (opens in a new tab) or Ask Perplexity (opens in a new tab).
Preferred sourceIf Google is your front door, you can add RankX AI as a preferred source (opens in a new tab), which asks your own results to surface more of what we publish.